Technology
How to Spot a Deepfake in a Video Interview or Zoom Call
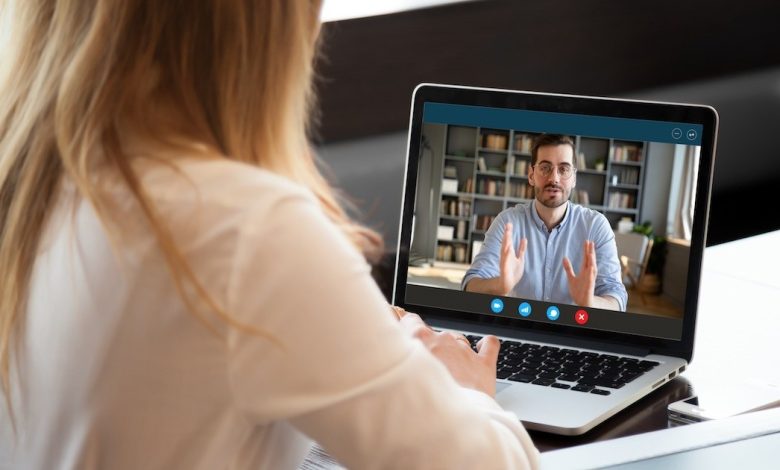
Video calls were long treated as the ultimate antidote to digital impersonation. If you could see a person’s face, watch their lips move, and hear their voice respond to your questions in real time, you could reasonably assume you were speaking to an actual human being. For years, this visual confirmation served as the foundation of remote hiring, vendor vetting, and executive approvals.
That assumption of authenticity is no longer safe. Generative adversarial networks and diffusion models have advanced from producing uncanny, static portraits to rendering high-definition, live-streamed synthetic personas. Today, malicious actors, fraudulent job candidates, and organized cyber syndicates deploy real-time face swaps and cloned voices during live video conferences. They bypass identity verification to land remote engineering roles, impersonate corporate executives to authorize wire transfers, and infiltrate secure internal systems.
Detecting a synthetic presence on a video call requires a shift from passive observation to disciplined, technical vigilance. While algorithmic generation has become remarkably sophisticated, live rendering remains bound by physical and computational constraints. By understanding how synthetic video breaks down under scrutiny, interviewers and business leaders can reliably spot the telltale flaws of a real-time deepfake.
The Architecture of Real-Time Video Manipulation
To catch a deepfake during a live call, you first need to recognize how real-time manipulation differs from pre-rendered video. High-budget synthetic videos seen in cinema or polished online hoaxes benefit from offline processing. Editors spend hours or days running thousands of frames through high-powered rendering farms, fixing frame-by-frame errors, smoothing lighting transitions, and matching audio tracks manually.
Live video affords an attacker no such luxury. A real-time deepfake tool operates under ruthless computational constraints. The software must capture the attacker’s webcam feed, identify facial landmarks, map a synthetic target face onto those coordinates, adjust for lighting and head angle, blend the synthetic perimeter into the real neck and hair, and push the processed feed into a virtual webcam driver—all within roughly 50 to 100 milliseconds.
Because consumer hardware must make drastic shortcuts to keep pace with a live 30-frame-per-second stream, the rendering engine leaves behind distinct visual and behavioral compromises. These flaws are often invisible to the casual observer, but they become glaringly obvious the moment you know where to look.
Visual Anomalies: Reading the Pixels
Real-time software struggles most where distinct biological features meet fluid motion. Focusing your gaze on specific facial zones will quickly reveal whether you are looking at organic tissue or a neural network’s best approximation.
Edge Blending and Boundary Warping
The perimeter of the face is the most vulnerable point of any face-swapping algorithm. Software must cut out the target face and stitch it onto the performer’s underlying head.
Pay close attention to the jawline, ears, hairline, and neck. When a subject turns their head, the model must guess where the synthetic cheek ends and the real background or neck begins. This creates micro-blurring, ghosting, or slight jitter along the edges of the face. In many instances, the skin tone of the face will not perfectly match the skin tone of the neck or ears, revealing a sharp, unnatural discoloration line right beneath the chin.
Ocular Dynamics and Gaze Tracking
Human eyes are mechanically complex and exceptionally difficult for real-time models to synthesize accurately. Synthetic eyes often exhibit subtle, unsettling inconsistencies.
Look for a lack of genuine convergence. When a real person looks at a screen or shifts their gaze, both eyes move in coordinated alignment, adjusting focal depth and pupil position simultaneously. In a deepfake, one eye may lag slightly behind the other, or the gaze may seem perpetually unfocused, staring through the lens rather than engaging directly with the screen.
Blinking patterns provide another critical clue. While early AI models struggled to blink at all, modern iterations have learned to incorporate periodic blinks. However, the movement is frequently mechanical. The eyelids may shut incompletely, appear blurry during the downstroke, or blink with a rigid, metronomic cadence that lacks the natural variation of human ocular moisture control.
Equally revealing is the reflection of light in the pupil. A person sitting in an office or home environment will reflect the surrounding environment—such as a monitor glow or window frame—identically in both eyes. Deepfakes frequently generate mismatched corneal reflections, displaying bright catchlights that point in conflicting directions or fail to change when the on-screen lighting shifts.
Micro-Expressions and Facial Anatomy
Real faces are constantly alive with involuntary micro-movements. Tiny muscles around the temples, eyebrows, and mouth twitch, flex, and pull during active conversation.
Synthetic overlays tend to homogenize these subtleties, producing what observers often describe as a porcelain mask effect. The central features—eyes, nose, and mouth—may move dramatically, but the surrounding cheeks, forehead, and bridge of the nose remain unnaturally smooth and stationary. When the subject smiles, notice whether the skin around their crow’s feet crinkles naturally or stays frozen.
Furthermore, real-time rendering struggles with interior mouth structures. Teeth in a deepfake often appear as a solid, pearlescent white bar rather than distinct, individual teeth. The tongue is frequently absent or rendered as a vague, dark pink smudge that blurs during rapid speech.
Auditory Disconnects and Articulation
Visual deception is only half the equation; synthetic personas almost always rely on real-time voice conversion or cloned audio profiles. While artificial voices can capture pitch and timbre effectively, they frequently fail the physics of speech production.
Phonetic Lip-Sync Failure
Producing certain consonant sounds requires specific, physical contact between the lips and teeth. Linguists classify sounds like P, B, and M as bilabial consonants because human lips must press completely flat together to produce the necessary air pressure.
Watch the subject’s mouth closely when they pronounce words containing these sounds. Real-time deepfake models often synthesize the audio correctly while the visual mouth opening fails to close completely. If you hear a crisp “P” or “B” sound while the speaker’s lips remain partially parted, you are witnessing an algorithm struggling to sync a synthetic audio stream to a predictive visual map.
Acoustic Flatness and Breathing Gaps
Natural human speech is messy. It contains breathing pauses, vocal fry, subtle throat clearances, and variations in volume based on head angle relative to the microphone.
Voice-cloning engines convert text or an attacker’s vocal input into the target speaker’s tonal model, but they frequently erase biological breathing markers. The speaker may deliver lengthy, uninterrupted sentences without the audible inhalation of air, or the background room tone may unnaturally cut to complete silence between syllables. If the voice carries a sterile, flat acoustic profile that does not match the visual environment—such as a hollow, echoey voice in a heavily carpeted room—the audio is likely being injected artificially.
In-Call Stress Tests: Breaking the Model
Passive observation can sometimes leave you second-guessing yourself, particularly if poor webcam resolution or low network bandwidth mimics synthetic artifacts. When you suspect a candidate or caller is using a synthetic persona, the most effective strategy is to introduce dynamic variables that overload the rendering pipeline.
Neural rendering models are trained primarily on front-facing imagery. They rely on predictable geometry. When that geometry is abruptly disrupted, the model breaks down in real time.
Ask the caller to turn their head completely to the side. A forty-five-degree tilt is rarely enough to defeat modern software, but a full ninety-degree profile view forces the algorithm to generate an angle where facial landmarks disappear from the webcam’s view. When a performer turns completely sideways, the software will frequently glitch, snap back to the attacker’s real face, or cause the synthetic nose and jaw to detach and float in mid-air.
Request that the person wave their hand slowly across their face. Neural networks rely on an uninterrupted line of sight to map facial coordinates. When an obstacle passes between the camera and the face—a process known as occlusion—the algorithm loses its anchor points. As a hand passes over the cheeks and mouth, the synthetic face will often warp, smear into the fingers, or disappear entirely for a fraction of a second until the hand clears the frame.
Introduce dynamic environmental lighting. Ask the participant to hold up a white sheet of paper next to their face or adjust a desk lamp. A real human face will immediately reflect the bounce light across its skin contours, shifting shadow lines instantly. A real-time face swap will struggle to recalculate the complex global illumination on the fly, leaving the facial lighting completely disconnected from the newly lit environment.
Institutional Safeguards for Remote Organizations
Relying entirely on an individual interviewer’s perceptual acuity is a fragile organizational defense. High-stakes environments—such as technical engineering hiring or treasury authorization—require standardized operational policies that preempt synthetic manipulation before it occurs.
First, implement multi-channel identity verification for critical operations. Never rely solely on an incoming video feed to authorize funds, issue credentials, or verify onboarding details. If an executive requests an urgent funds transfer via video, require a secondary verification through a separate, secure channel using hardware security keys or a confirmed internal messaging system.
Second, audit the peripheral metadata of video candidates. Fraudulent applicants using real-time video injection software must route their camera feed through virtual webcam software like OBS or custom capture drivers. Screen sharing during an interview should include viewing the candidate’s peripheral display settings and system processes, where active rendering software and virtual video drivers will readily appear.
Finally, normalize active questioning during initial technical screenings. Deepfake operators who sit as proxies for unqualified candidates rely on prepared scripts and remote confederates whispering answers. Asking hyper-specific, conversational questions that require rapid whiteboard sketching, physical problem solving, or immediate verbal improvisation forces the operator to split their attention, causing their visual rendering tools and audio translation feeds to stumble under the cognitive load.
The Future of Visual Trust
The era of effortless visual trust has drawn to a definitive close. Real-time deepfakes have progressed from theoretical laboratory experiments into accessible, commoditized tools used for corporate deception, financial fraud, and credential theft.
Maintaining digital security does not require retreating into skepticism or abandoning remote workflows. It requires cultivating an informed, disciplined awareness of how synthetic tools operate. By pairing an eye for visual rendering flaws with active in-call challenges and rigorous verification protocols, organizations can effectively defend their perimeters, ensuring that the individuals on the other side of the screen are exactly who they claim to be.